Hugging Face Releases Benchmark to Evaluate How Effectively AI Agents Use Software Tools
Hugging Face has introduced a new evaluation methodology that measures the entire execution process of AI agents rather than just final outputs. This approach helps developers assess how effectively agents leverage specific software libraries and internal tools instead of bypassing them.
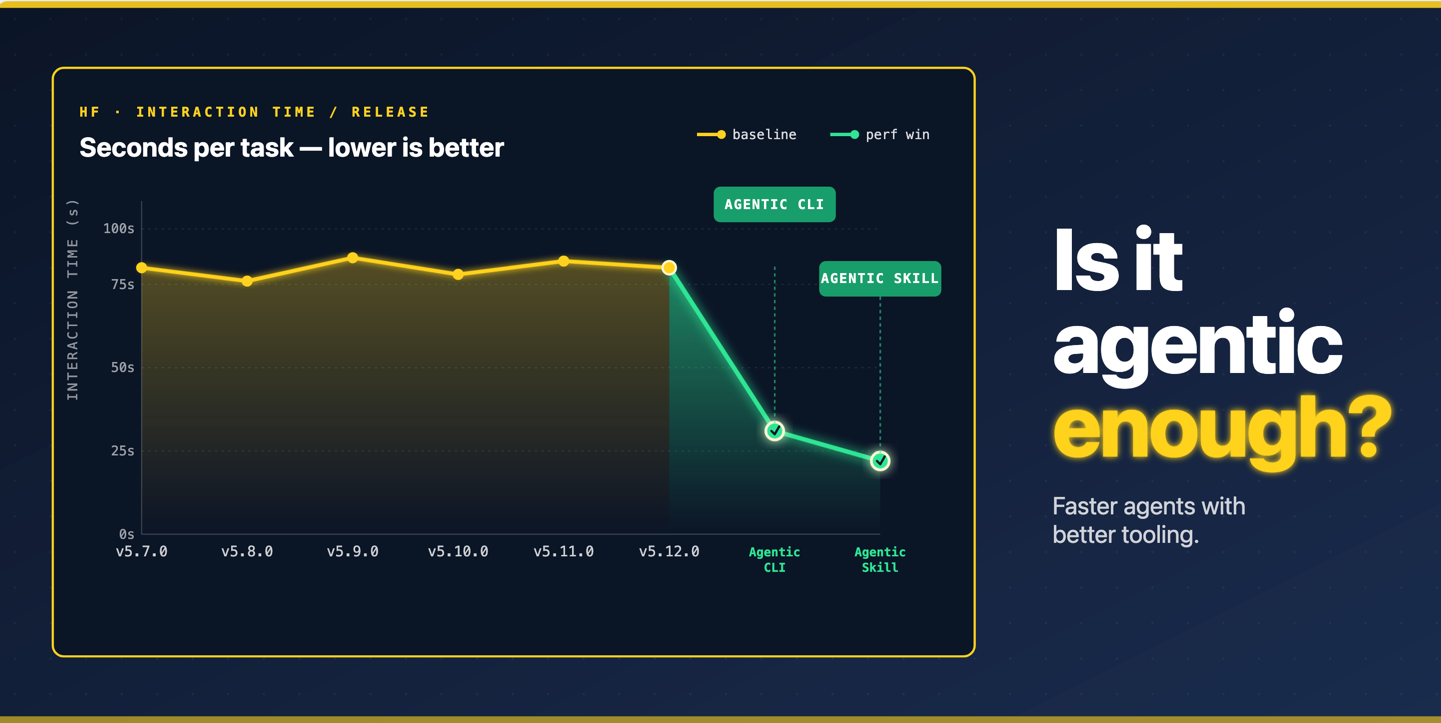
Hugging Face has published a new benchmarking method designed to evaluate how effectively AI agents utilize proprietary development tools and libraries. While traditional benchmarks focus almost exclusively on whether the final answer is correct, this new methodology tracks the entire execution process. It records key performance metrics such as the number of reasoning steps, debugging attempts, and specific API calls made to complete a task. During testing with the transformers library, researchers observed that agents often bypass complex library functions and rewrite the underlying logic from scratch when they struggle to use the provided tools. This behavior varies significantly based on model size and library versions. Larger models tend to show performance variations across different library revisions, whereas smaller models exhibit prominent performance gaps between different model providers. For developers building custom CLI tools or libraries for AI agents, simply exposing API endpoints is no longer sufficient. This benchmark provides an objective way to measure the usability of software tools for agents, ensuring that models can reliably select and execute the intended functions. By integrating this evaluation, developers can optimize their developer experience specifically for LLM-driven consumption.
Primary source
Open Hugging Face Blog ↗This article summarizes the source. Check the original for full details and conditions.
Comparison
| Aspect | Before / Alternative | After / This |
|---|---|---|
| Primary Metric | Final output accuracy only | Step-by-step execution path, including tool call sequences |
| Tool Usage Tracking | Undetected, focusing only on whether the goal is achieved | Monitored, identifying if agents bypass APIs to write custom logic |
| Debugging Evaluation | Ignored in the final evaluation score | Quantified by counting error-handling and code-correction steps |